The shift
Why voice alone cannot complete complex workflows
Some enterprise workflows stay manual because finishing them takes more than just talking. Voice agents cover the conversation but stop where a decision needs sight, and moving that to a separate step loses the shared context. Multimodality lets one agent reason across voice and vision together, so the workflow actually finishes.
Why one pipeline
How a multimodal agent handles voice and vision in one conversation
Combining the two modalities in one pipeline changes both what the agent is capable of and how much infrastructure your team has to build and maintain.
Shared context across modalities
Because the image and the audio move through the same pipeline, the agent interprets what it sees in light of everything the person has already said. A photo is never treated as an isolated request.
Less orchestration for your team
Your developers no longer coordinate separate model calls or pass conversation state between a speech system and a vision system. The inputs are already together when they reach the agent.
A complete record you can review
Every interaction is captured with the spoken exchange and the visual inputs aligned on a single timeline in Lens, so your team can replay exactly what the agent heard and saw.
Industries
Every industry has a call that stalls because the agent cannot see. A multimodal agent finishes it.
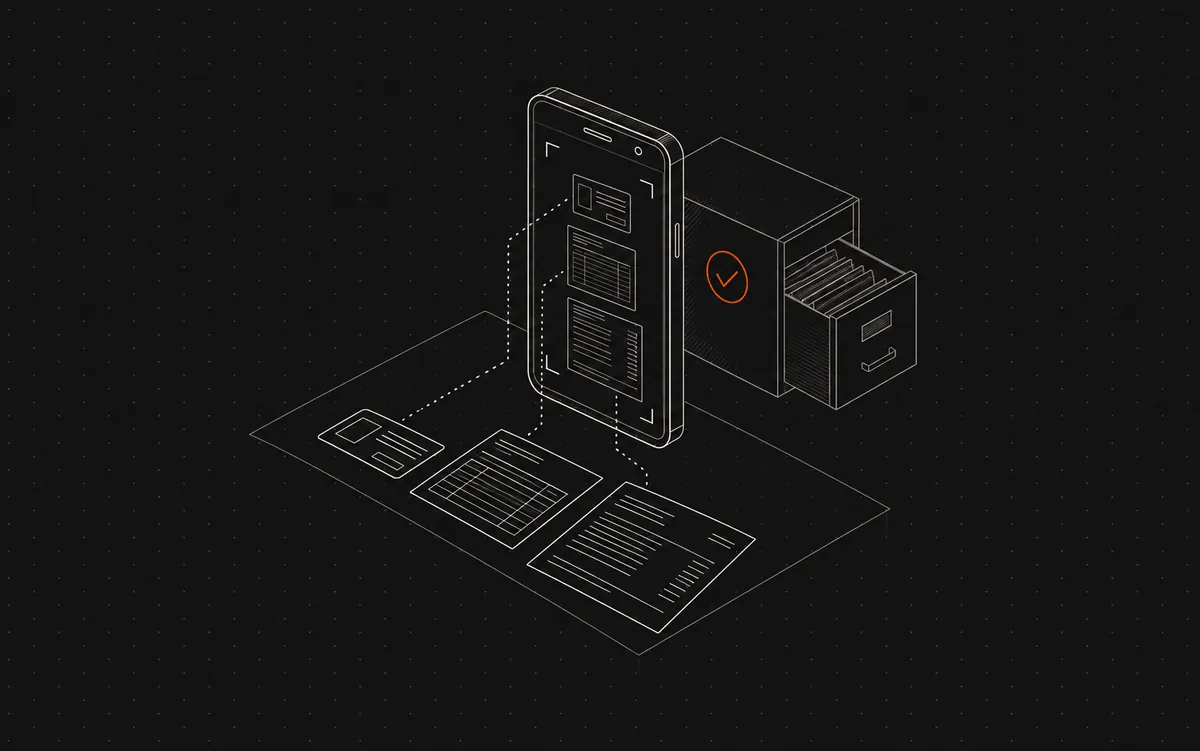
Loan application, documents collected on the call
What happens: an applicant calls about a personal loan. The agent asks them to hold their ID, a pay stub and a bank statement up to the camera, reads the name, employer, income and address straight off each image, checks them against what the applicant said and the application already on file, and flags any mismatch while they are still on the line.
The outcome: the application is complete and verified when the call ends, so approval that used to wait days for paperwork happens same-day. Approval turnaround drops from days to the length of the call.
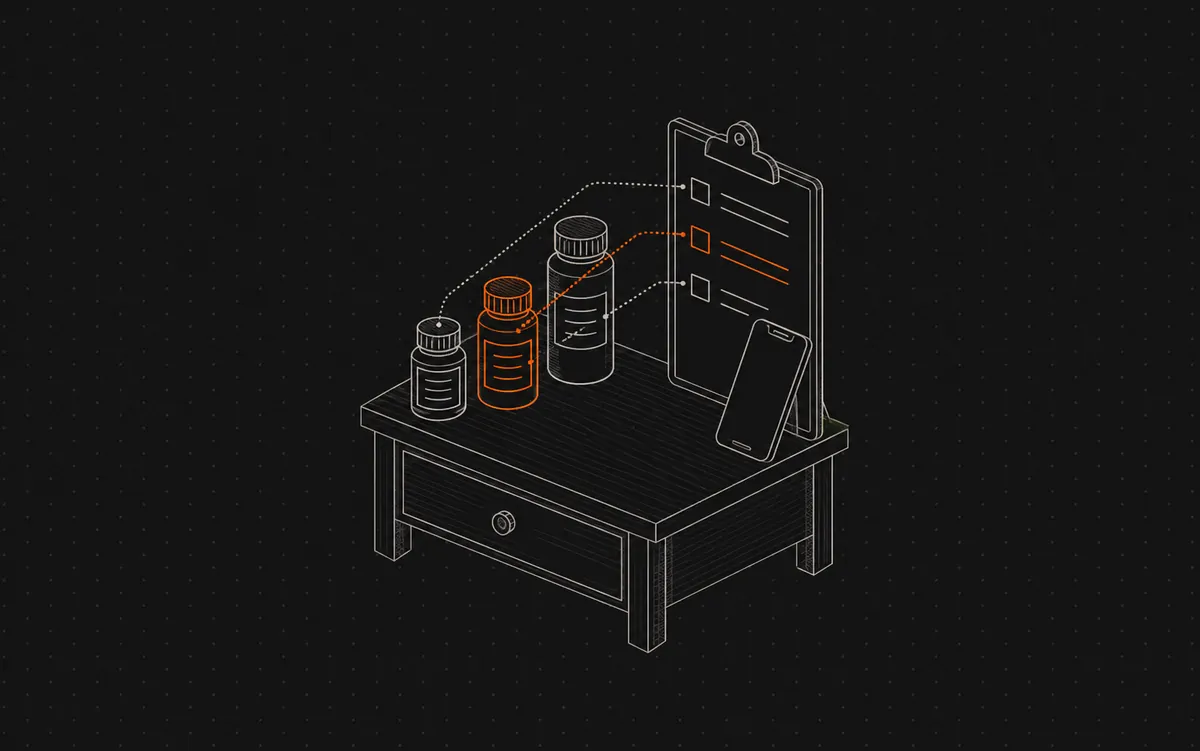
Post-op medication check
What happens: on the recovery check-in call, the agent asks the patient to hold each medication bottle up to the camera, reads the drug name and dose off the label, and compares them against the discharge plan it already has. Anything missing, doubled or wrong is flagged to the care team while the patient is still on the line.
The outcome: a medication error gets caught on the call instead of sending the patient back to the hospital. Fewer 30-day readmissions.
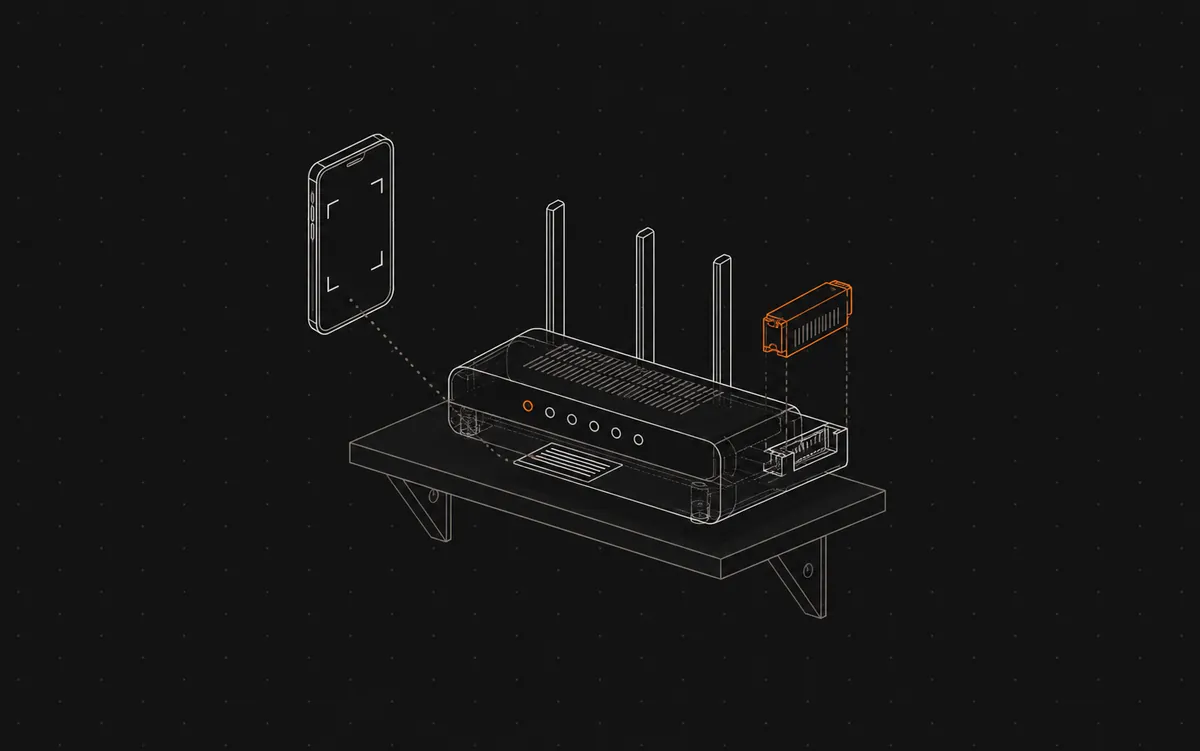
Product support without the truck roll
What happens: a customer calls because their router keeps dropping. The agent asks them to point the camera at it, reads the model and serial off the label, sees which light is blinking, and walks them through the fix for that exact unit. If a part is dead, it orders the replacement against the serial it just read.
The outcome: the exact unit gets fixed while the customer is still on the line, instead of dispatching a technician. Higher first-call resolution.
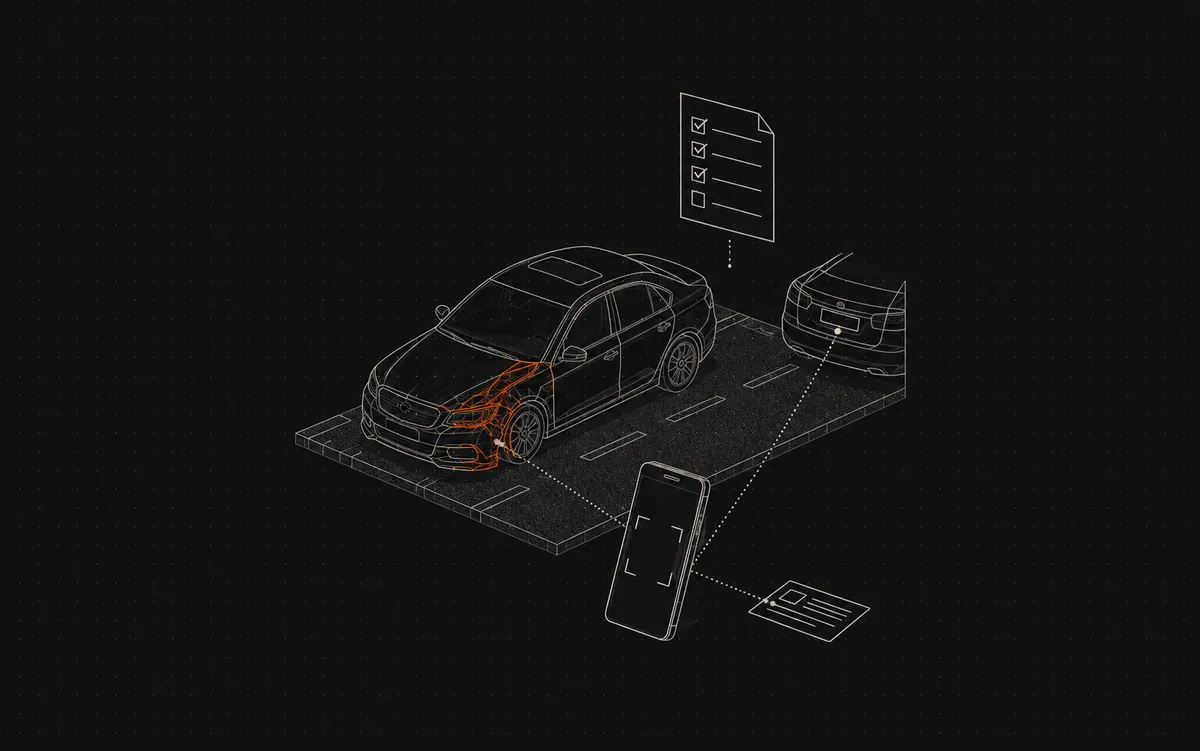
First notice of loss, filed on the call
What happens: a driver calls after a collision. The agent asks them to show the damage, the other car's plate and the other driver's insurance card on camera, reads the plate and policy details off the images, attaches the damage photos, and opens a complete claim while the driver is still at the roadside.
The outcome: the claim is complete the moment it opens, so it goes straight to assessment instead of a queue of follow-up calls. The claim settles in days, not weeks.
Foundation
Built on DinoDial's voice AI harness
Multimodality is a deliberate extension of the work DinoDial has already done in voice, rather than a separate product bolted on beside it. The real-time, low-latency, full-duplex foundation we built across a million production calls is the same foundation that now carries visual context. The harness your team already uses to ship reliable voice agents is the one that lets those agents see.
FAQ
Frequently asked questions about multimodal AI agents
- What is a multimodal AI agent?
- A conversational agent that works with more than one type of input in the same interaction. A DinoDial agent combines live voice with images or camera frames the person shares, and responds based on both together.
- How do you add vision to a voice AI agent?
- You enable visual input on an existing voice agent instead of building a separate vision system. The person can upload a photo or share their camera during the call, and those frames travel through the same pipeline as the audio.
- How is this different from sending an image to a separate model?
- A separate model analyzes the picture in isolation and returns a result outside the conversation. A multimodal agent brings the image into the live interaction, so it is interpreted alongside what the person has already said.
- What can a multimodal AI agent see during a call?
- A still photo, or the device camera at up to one frame per second. DinoDial resizes the images and delivers them to the agent alongside the live audio.
- Which models power multimodal agents on DinoDial?
- DinoDial connects to multimodal models, including Gemini Live, through a single adapter. The agent receives the combined voice and visual input through the same interface it already uses for voice.
- Can you review the voice and image inputs from an agent call?
- Yes. Every call is recorded with the spoken exchange and the visual inputs aligned on one timeline in Lens.
Build multimodal AI agents on DinoDial
If your product depends on interactions where people need to be seen as well as heard, DinoDial gives you the pipeline to build those agents on the voice foundation your team already trusts.